---
title: "Keeping an AI Agent Inside Its Personal-Information Boundaries: What Meta's PrivacyLib Shows About Making PIPL Purpose Limits Work at Runtime"
author: "DCC Editorial"
published: 2026-10-28T12:00:00.000Z
url: https://datacompliancechina.com/posts/agent-pi-boundaries-meta-privacylib/
description: "On October 27, 2026, Meta described PrivacyLib, a layer of its privacy infrastructure that enforces privacy rules where backend services actually read and write data. AgentLib ties each agent tool call to its session, so the check happens even when an agent strings tools together in ways no developer anticipated. 网安寻路人 uses the disclosure to answer a question the PIPL leaves open for agents: how do you hold a system whose execution path unfolds at runtime to Article 6's purpose and minimum-necessity limits and Article 13's legal bases? The author's answer has five parts. Turn the user's task into concrete processing boundaries, set by trusted business systems rather than the model. Check every operation where data actually flows, not at the final answer. Carry provenance and use conditions onto derived content (summaries, vectors, long-term memory), and re-classify when inference yields sensitive personal information. In agent-to-agent delegation, grant only the intersection of the upstream's delegable scope, the sub-agent's own permissions, and the subtask's needs; keep control instructions apart from business data; and map each tool to its legal role under Article 21 (entrusted processing) or Article 23 (provision to another handler). And make the rules themselves current, revocable, and auditable. Five diagrams from the original are included."
tags: ["ai-agents", "purpose-limitation", "privacy-engineering", "meta", "privacylib", "prompt-injection", "pipl-article-6"]
laws_cited: ["pipl"]
domains: ["ai-governance", "personal-information"]
account: "wangan-xunluren"
original_title: "智能体处理个人信息的边界如何持续有效——从 Meta PrivacyLib 看个人信息保护的运行机制"
original_author: "网安寻路人"
original_publication: "网安寻路人 WeChat Official Account"
original_url: "https://mp.weixin.qq.com/s/nN-CIEKLbSD_3zBigKPXpw"
source_language: "zh"
---
> **Source: Data Compliance China** — https://datacompliancechina.com/posts/agent-pi-boundaries-meta-privacylib/ · China data law, translated and annotated for overseas counsel. Cite as: Data Compliance China, "Keeping an AI Agent Inside Its Personal-Information Boundaries: What Meta's PrivacyLib Shows About Making PIPL Purpose Limits Work at Runtime", https://datacompliancechina.com/posts/agent-pi-boundaries-meta-privacylib/
> *Editor's Note — DCC.*
>
> This brief translates an essay published by 网安寻路人 on October 28, 2026.
> The post names no author; "we" below is the account's author (公号君). Its
> subject is an engineering disclosure, not a Chinese rule: Meta's October
> 27, 2026 description of **PrivacyLib**, the part of its privacy
> infrastructure that enforces rules at the data-access layer. But the
> essay is a reading of the
> [Personal Information Protection Law](/laws/pipl/). It asks how the PIPL's
> purpose and minimum-necessity limits (Article 6), its legal bases (Article
> 13), and its split between entrusted processing (Article 21) and
> provision to another handler (Article 23) can actually hold when an AI
> agent decides its own execution path at runtime.
>
> Descriptions of PrivacyLib, AgentLib, Policy Zones, and Agent
> Observability are the author's reading of Meta's materials, as are the
> references to the CaMeL architecture and the October 2026 preprint *Can
> CaMeLs Talk?*. DCC has not independently reviewed those sources. The five
> diagrams are reproduced from the original post, in Chinese, each followed
> by DCC's English reading. DCC has dropped the account's list of past
> articles on agents that opens the post. For DCC's earlier pieces on
> agents and consent, see
> [AI Agents and the Limits of Consent](/posts/ai-agents-and-the-limits-of-consent/)
> and the
> [TC260 agent-deployment practice guide](/posts/tc260-ai-agent-deployment-security-guidelines/).
Suppose a user tells an agent: "Sort out last week's travel expenses and
submit the claim." To do it, the agent has to read emails, extract
receipts, check the itinerary, and then call the company's expense system.
For the user, it is one instruction. Inside the system, it unfolds into a
chain of personal information processing. Which emails may be read,
whether receipts need to go to an external model for processing, whether
the resulting spending records can be saved to long-term memory: these
are often not fixed before the task starts. They are settled step by step
as the task runs.
That raises a direct, concrete question for personal information
protection. When a task's execution path has not yet unfolded, how should
the boundaries of personal information processing be drawn? And while the
path keeps changing, how do you make sure those boundaries stay effective?
On October 27, 2026, Meta publicly described PrivacyLib, part of its
privacy infrastructure. The mechanism embeds the enforcement of privacy
rules directly in the underlying data-access layer. Through AgentLib, it
links an internal agent's tool calls to the current session, so that
downstream systems can decide in real time, from the call context and the
data's annotations, whether to let an operation through. On paths that
have been integrated and have controls switched on, even a combination of
tools the developer never anticipated must pass a compliance check as soon
as it touches data access.
In our view, what makes this practice worth attention is that it offers a
workable implementation path for a problem that usually stays at the level
of principle. An agent can decide for itself how to plan its steps and
finish the task, but its authority to process personal information has to
be verified at every concrete data operation. In other words, an agent's
autonomy can extend to how it executes a task. It cannot extend, on its
own, the purpose or scope of personal information processing.
## I. Task authorization has to come down to specific processing acts
Go back to the expense claim. Permission to read the receipts for this
trip is not permission to analyze the employee's spending habits over the
past year along the way. Permission to call a search tool is not
permission to put the employee's name, hotel, and spending details into a
search query and send it out. Even where each tool is available on its
own, using them in combination can create information flows that go
beyond the task as given.
The gap arises because "tool permissions" and "personal information
processing permissions" answer different questions. The first is about
what the system can technically call. The second goes further: whose
information, which information, for what purpose these capabilities may
be used on, and to whom the results may go. So even when the same person
uses the same tool, a change in the processing purpose or the recipient
changes the conditions under which the operation is lawful and compliant.
Article 6 of the PIPL requires that personal information be processed for
a clear and reasonable purpose, directly related to that purpose, and
limited to the minimum scope of collection necessary. Article 13 requires
a legal basis for every processing activity. Seen in an agent setting,
"the user gave a task instruction", "the current account can technically
access the data", and "the specific processing act has a legal basis" are
three different questions, to be judged separately. An employee who says
"help me analyze these customers" can start a business request. But the
system cannot, on that sentence alone, hand customer data to a new
external service provider or turn it to another line of business. At
runtime, each operation should be tied to the legal basis that applies to
it, and checked against that basis for notice, consent, and the other
legal conditions.
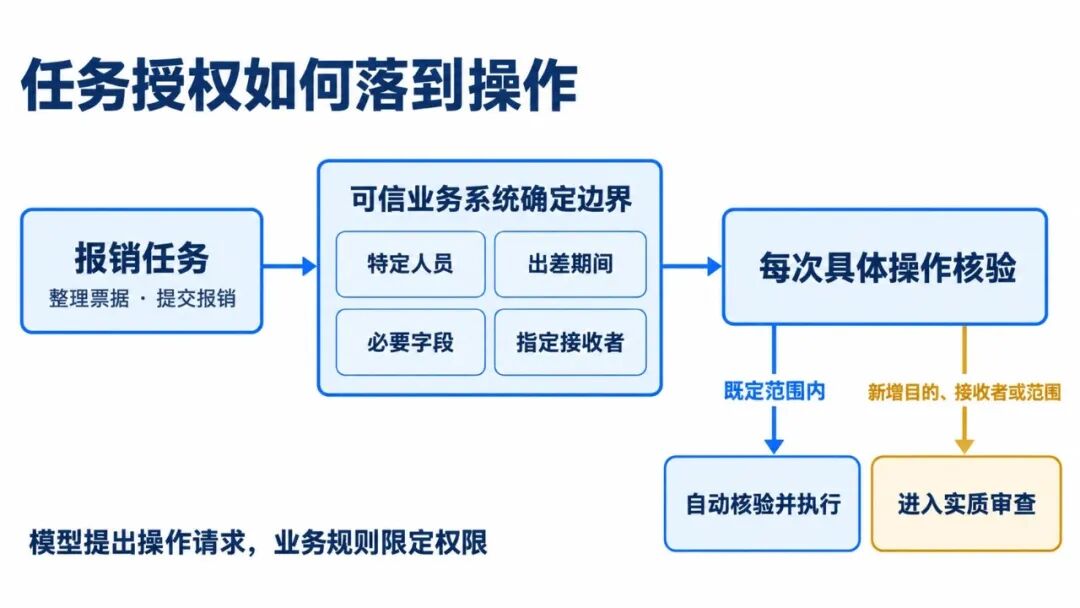
So a key step in designing an agent is to turn the user's task into
processing boundaries the system can enforce. For the expense claim, the
system should fix it as a specific person, a specific travel period, and
the fields necessary for the claim, and allow submission only to the
designated expense system. If an external model genuinely needs to help,
the system should decide in advance what content that model provider may
receive. These boundaries are set first by trusted business systems and
permission mechanisms, and they are the yardstick for whether any later
operation goes through. At runtime, the model can request to read or send
data. It cannot, to get a request approved, change the task's purpose
settings mid-execution.
Does this mean every tool call needs a pop-up for the user to approve one
by one? No. Operations within an already-defined purpose and scope can be
checked and executed automatically and continuously by the underlying
system under the existing rules. Additional, substantive review is needed
only when the task genuinely requires a new processing purpose, a new
recipient, or a wider scope of information. That way the user's real
decision runs through the whole task, without turning complex technical
calls back into a long string of "consent" buttons that wear users out and
that they cannot really judge.
Figure 1 | How task authorization comes down to operations
Diagram from the original post, in Chinese. DCC's English reading follows.
*DCC's English reading.* The expense-claim task (sort receipts, submit the
claim) goes to a **trusted business system that sets the boundaries**:
specific person, travel period, necessary fields, designated recipient.
**Every concrete operation is then checked.** Operations within the set
scope are verified and executed automatically; a new purpose, recipient,
or scope goes to substantive review. The model proposes operations;
business rules limit what it may do.
## II. Put the check where data actually flows
If processing boundaries have to be checked continuously at runtime, where
should the check sit? PrivacyLib's answer is to put a common checking
mechanism in the data-access client libraries that backend services use.
"Client" here does not mean an end-user application. It means the software
libraries backend services use to reach databases, logging systems, and
other underlying infrastructure. That position sits exactly at the gate
through which data flows. It knows which data asset an operation will
touch, and it can obtain the runtime context (the caller, the endpoint,
the processing purpose). That makes it the best place to judge each
concrete data operation.
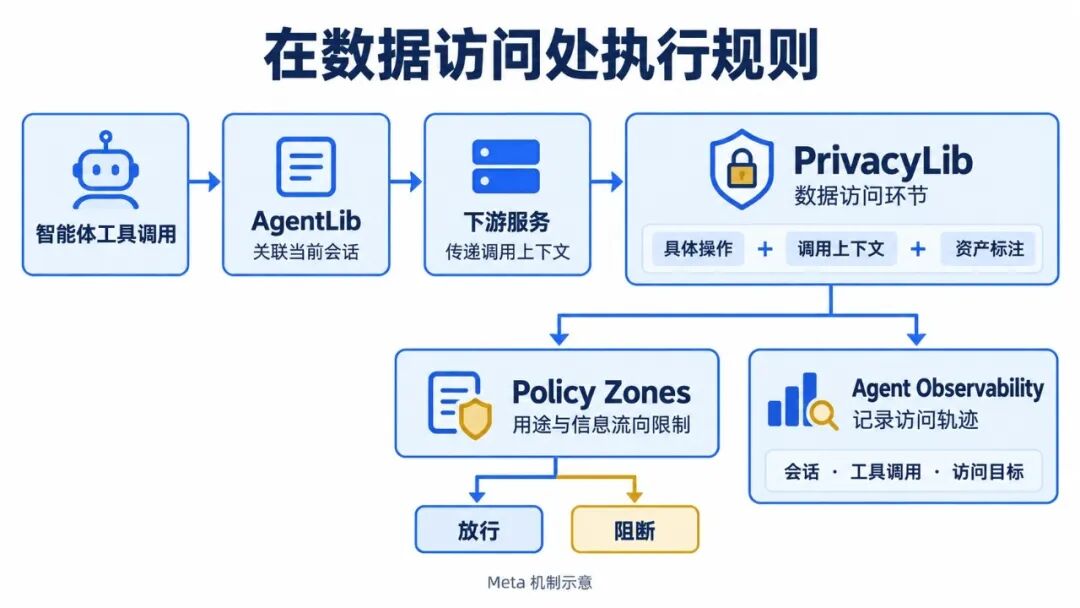
In the runtime flow, once an agent makes a tool call, AgentLib first links
that call to the corresponding agent session, and downstream services pass
the context along the call chain. When the request reaches the data-access
layer, PrivacyLib hands the operation, the call context, and the target
data asset's annotations to the relevant modules. **Policy Zones** enforce
restrictions on purpose and information flow. **Agent Observability**
records the session identifier, the tool calls, the access targets, and
similar details, so that it can be established afterward which systems the
data actually passed through. In short, "deciding whether to let it
through" and "recording the access trail" are separate jobs in the system.
Figure 2 | Enforcing rules at the point of data access
Diagram from the original post, in Chinese. DCC's English reading follows.
*DCC's English reading (illustration of Meta's mechanism).* Agent tool
call → **AgentLib** (links the current session) → downstream services
(pass the call context) → **PrivacyLib** at the data-access layer
(operation + call context + asset annotation). PrivacyLib feeds two
modules: **Policy Zones** (purpose and information-flow limits, which
allow or block) and **Agent Observability** (records the access trail:
session, tool calls, access targets).
Meta's technical post uses the writing of message metadata as an example
of how the decision happens. When the system is about to write data, it
checks both whether the current call context is one in which message
metadata may be used, and whether the target table carries the
corresponding compliance annotation. With enforcement mode on, if either
condition fails, the record is blocked before it is sent downstream. The
design constrains both the data's "current use" and its "onward
destination": even if processing is allowed at this step, the system still
has to make sure the downstream target can carry the same protective
restrictions.
This makes clear the pivotal role of **data annotation** in the whole
mechanism. Annotations connect data assets to the privacy rules that apply
to them, so different business services can understand and enforce the
restrictions with consistent meaning. When Meta earlier introduced Policy
Zones, it set out that the protections on downstream data should in
principle be no weaker than those on its upstream source, and it put the
creation, association, and removal of annotations under dedicated
governance. Protective conditions can thus follow information all the way
downstream. A caller cannot erase an existing purpose restriction simply by
storing the data in another table or deleting a label.
Putting rule checks at the actual point of data access also answers, at
the level of architecture, the problem that an agent's execution path is
hard to foresee. In a complex task, the agent's combination of tools can
keep changing. But however the path shifts, any read, write to storage, or
request to another service eventually has to pass through a specific
underlying interface. PrivacyLib maps read and write operations across
heterogeneous systems onto a common policy-enforcement model, so new
protection rules can reuse existing checkpoints. For supported direct
remote procedure call (RPC) paths, verification at a lower-level boundary
adds further coverage.
The lesson for agent compliance design is clear. Make every path that
actually produces a data-processing effect go through a single check, and
decide strictly by the processing purpose, data scope, and recipient
conditions fixed in advance. Then even if untrusted external text induces
the model, through prompt injection or otherwise, to propose a new
out-of-bounds operation, the model does not thereby gain the authority to
change the underlying verification conditions. The model chooses the next
business action; the enforcement layer verifies whether that action
crosses the legal boundaries of personal information processing. The two
have separate permissions and clear, separate jobs.
## III. After information is processed, its original limits must carry over
Once personal information enters an agent workflow, it often changes form.
A few original receipts become an expense summary. A string of emails is
condensed into a description of a person. Everyday chat logs are turned
into high-dimensional vectors and stored in long-term memory. The question
follows: after this processing, do the original purpose restrictions still
apply?
If the control system only recognizes original files or original tables,
it leaves an obvious loophole. Say the rules forbid sending original
receipts to an external search service. After reading the receipts, the
agent can simply restate the employee's name, travel route, and spending,
and send that as a search query. On the surface, the file name and wording
have changed; the personal information, and its effect on the individual's
rights and interests, are still there. More importantly, the moment the
agent writes the summary into the search parameters and sends the request,
the data has already gone to the external service. Filtering content only
when the final answer is generated for the user cannot undo a non-compliant
transfer that has already happened.
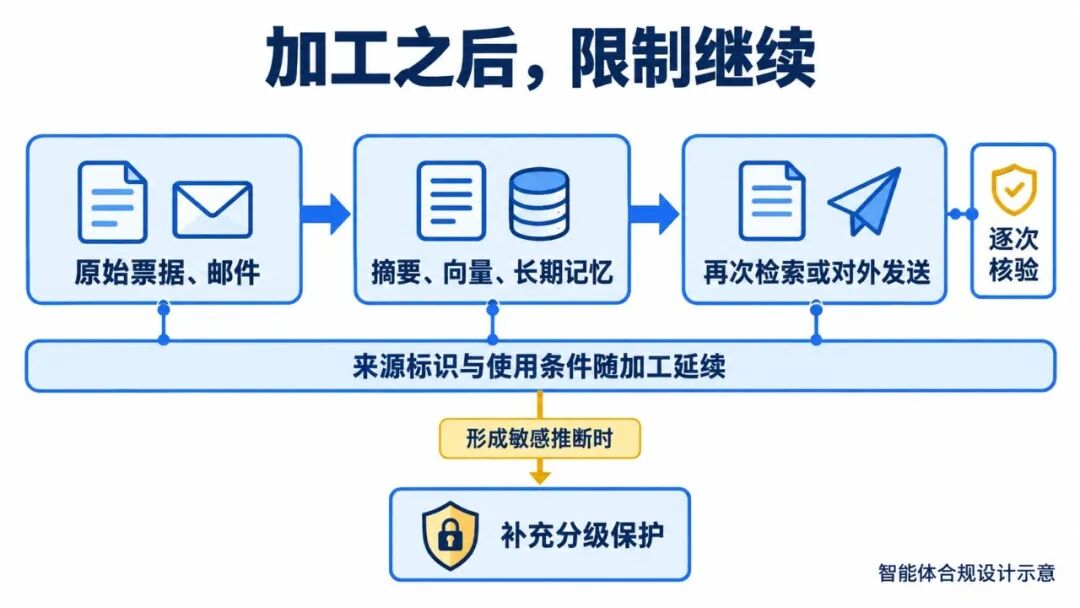
So an agent system designed along the lines of Policy Zones should carry
the restrictions over onto derived content as the data is processed. A
practical starting point is for outputs during a task to keep, by default,
the provenance labels and use conditions of the inputs. If the business
needs more flexibility in later use, tracking can be made more granular,
identifying which fields or computed results in an output actually depend
on which restricted sources. The systems that handle text summaries, vector
databases, and long-term memory must, in turn, be able to read these
attached conditions and enforce them strictly whenever the derived content
is called, retrieved, or delivered externally.
Security research on the **CaMeL** architecture offers a useful
implementation reference here. It uses an interpreter that sits outside the
model itself to maintain, for each runtime data variable, metadata on its
provenance and who may read it. It propagates dependencies automatically as
computation proceeds and enforces security policy before every tool call.
The mechanism shows that "in what form the model uses the data" and "to
whom the data may then be given" can be separated in a system and judged
separately.
Normatively, processed content also calls for a further distinction
between two situations. In the first, the original personal information has
only changed its wording or medium; the existing protections must be
maintained and fully inherited. In the second, pieces of information that
were scattered have been combined and reasoned over to form a new judgment
about a person's attributes, and the result has to be classified afresh.
Simply totaling an employee's spending, for example, is a very different
matter from inferring a particular person's health condition from those
records. The latter has produced an inference that is sensitive personal
information. It requires both that the original use restrictions carry over
and that the new information be classified and given upgraded protection.
Figure 3 | After processing, the restrictions continue
Diagram from the original post, in Chinese. DCC's English reading follows.
*DCC's English reading (illustration of agent compliance design).* Original
receipts and emails → summaries, vectors, long-term memory → retrieval or
external sending, **checked at each step**. Underneath all three, **provenance
labels and use conditions carry over through processing**. When a sensitive
inference is formed, **additional tiered protection** is applied.
Adjusting or lifting restrictions on derived content, likewise, needs a
clear basis and separate authority. Only when a data transformation
genuinely meets predetermined conditions for de-identification,
anonymization, or aggregation and de-sensitization may the system
reclassify it on
that basis. What reclassified data may then be used for, and to whom it
may go, must still be set by the applicable rules. That is why Meta puts
"reclassification" under a dedicated governance process, so label changes
are independently constrained. In an agent setting, the point is just as
simple: an agent writing "the above has been anonymized" into its own
context can never substitute for a compliance judgment at the system level.
## IV. Delegation between agents must keep permissions and provenance
In more complex scenarios, a lead expense agent may hand receipt
classification to a second agent and the check for missing materials to a
third. Each delegation reduces the complexity any one agent handles, but it
also lengthens the chain along which personal information flows. If, at
handover, the downstream agent receives only a natural-language instruction
("please process these materials"), the processing purpose, scope of
subjects, and recipient restrictions fixed for the original task are easily
lost along the way.
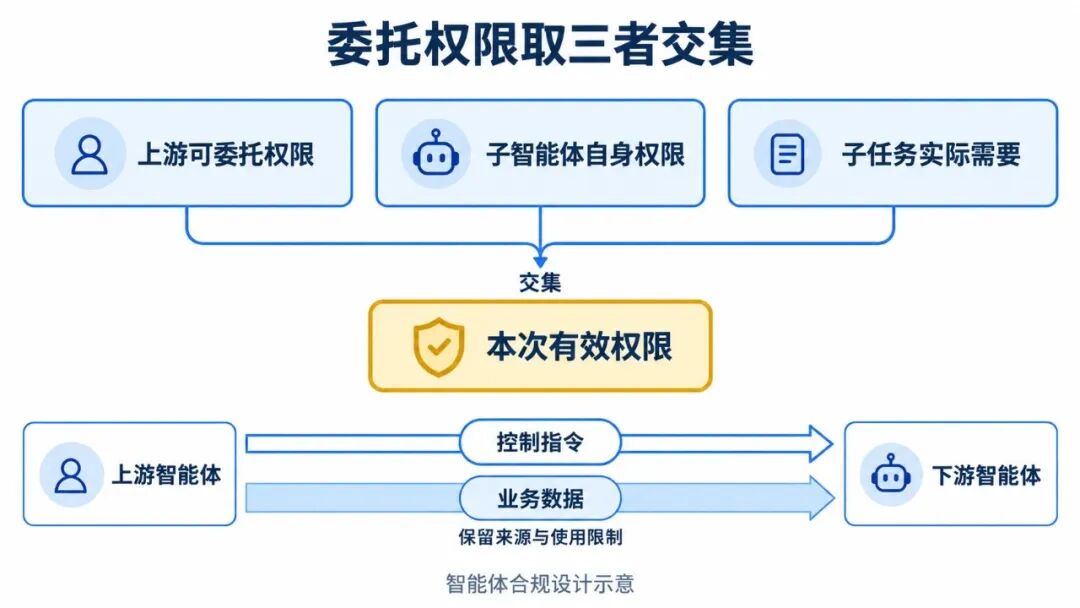
Delegation between agents therefore has to pass two kinds of information
downstream together. One says what the downstream agent is *allowed to do*
in this subtask. The other says where the materials it receives *came from
and what restrictions already attach to them*. Concretely, the processing
scope a sub-agent actually obtains in a given task should be bounded by
three things together: the permissions the upstream agent may delegate,
the sub-agent's own system permissions, and what the current subtask
actually needs. Even if a sub-agent is configured to access a broader
database, the upstream agent cannot use delegation to borrow those higher
permissions and widen the current task's processing scope.
Beyond the permission boundary, continuity of provenance matters just as
much. A preprint released in October 2026, *Can CaMeLs Talk?*, shows a
typical cross-agent risk. Content the upstream agent treats as "untrusted
external data", once written into a natural-language task description sent
to a downstream agent, is often executed by the downstream agent as a
"trusted instruction" from upstream, so an attack can be relayed from agent
to agent. The paper proposes containing this hidden "trust escalation" by
separating the channels for control instructions and business data, and
by preserving provenance continuously between agents.
For personal information protection, this security finding is directly
instructive. Text from an invoice, an email, or a web page should keep its
identity in the system as "task material" throughout. It must never, by
being summarized or restated by an agent, turn into a "control instruction"
with the authority to rewrite the task's scope, name a new recipient, or
direct that the data be used for something else. Only if every handover
preserves the original processing conditions and provenance intact does the
downstream agent have a basis for judging whether it may accept the
materials, within what scope it may use them, and to whom it may pass them
on.
Figure 4 | Delegated permissions are the intersection of three scopes
Diagram from the original post, in Chinese. DCC's English reading follows.
*DCC's English reading (illustration of agent compliance design).* **Upstream
delegable permissions** ∩ **the sub-agent's own permissions** ∩ **the
subtask's actual needs** = the **effective permissions for this
delegation**. Between the upstream and downstream agents, **control
instructions** and **business data** travel on separate channels, and the
business data keeps its provenance and use restrictions.
Going further, the delegation relationships in the technical architecture
must also line up precisely with the relationships between processing
parties in law. A cross-agent call may be a division of labor between two
agent modules inside one company, or it may cross an organizational
boundary and submit materials to another company's model service. The law
treats these completely differently. Articles 21 and 23 of the PIPL set the
legal requirements for "entrusted processing" and for "providing personal
information to another personal information handler" respectively. An agent
platform's tool catalog should therefore record, alongside each tool's
technical interface parameters and functional description, the
organization behind the interface, its actual processing role, and the
processing scope agreed by contract. Only then can the runtime chain of
technical calls be translated into a clear, verifiable chain of legal
responsibility.
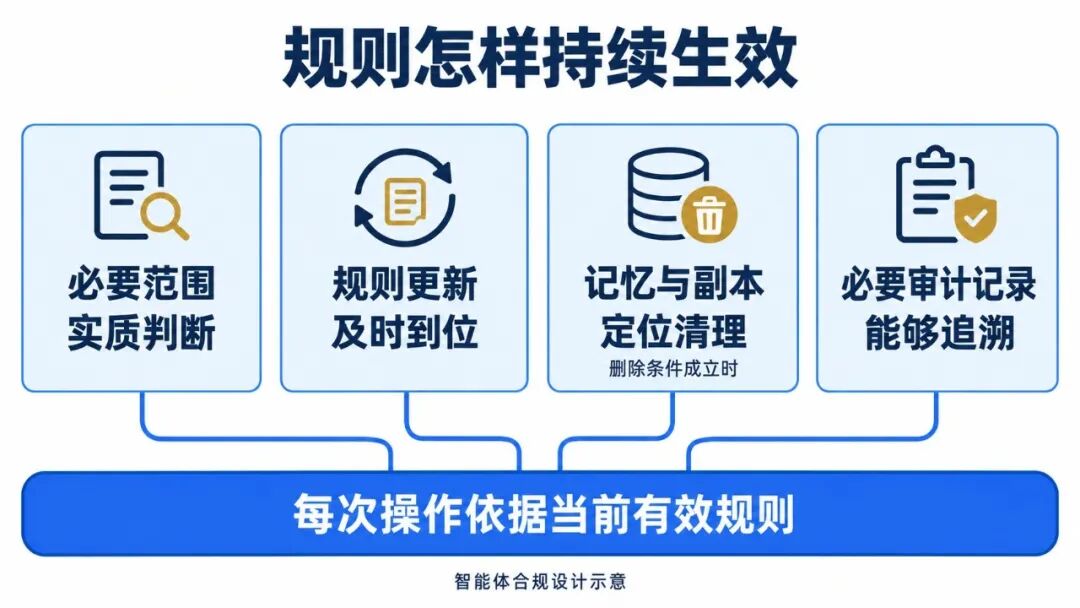
## V. Making the rules hold while the system runs
Whether data labels or call context keep working at runtime comes down,
ultimately, to who makes the rules behind them, who may change them, and
how changes reach every point of enforcement accurately. Automated
technical enforcement is thus tied closely to organizational compliance
governance. To make the rules hold while the system runs, four things
matter most.
**First, the definition of processing purposes and necessary scope needs
substantive judgment behind it.** A label-checking mechanism does not by
itself produce reasonableness. Suppose the expense system always carries the
"expense claim" label correctly, but the rule behind it allows reading all
of the employee's email, all their spending records, and even their family
members' information. Then however accurately the underlying mechanism
works, it is only precisely enforcing a rule that is too broad. Building an
agent system should therefore start from the substantive relationship
between a specific business task and the data it needs, and produce a
verifiable correspondence between business needs, legal assessment, and
technical configuration. A blanket "the model might need it when reasoning"
cannot stand in for a statement of necessity.
**Second, system rules must change promptly as the task progresses and as
individuals' rights change.** In its engineering, PrivacyLib uses caching
and per-service deployment to reduce runtime cost and contain the impact of
rule changes. When the mechanism is used for personal information
protection, policy versions, deployment scope, and cache invalidation have
to be managed too, so that every later operation is decided under the rules
currently in force. For example, once the task authorization a data read or
external send relied on has ended, or the individual has lawfully withdrawn
consent, the system may no longer rely on a past "allow" result based on that
earlier authorization or consent.
**Third, an agent's long-term memory and data deletion need to be dealt
with separately.** Temporary processing needed to complete one expense claim
is very different, in processing scope and retention period, from keeping
the materials in long-term memory for future tasks. The system should
record, at the underlying layer, the mapping between long-term memory,
text summaries, and vector indexes and their original data sources. When
the applicable deletion conditions are met, it can then locate and clear
the relevant content precisely. Where laws or administrative regulations
require retention, it should restrict further use accordingly and block
later retrieval and calls at runtime. In short, "stopping further access"
and "dealing with existing copies" each need their own technical actions.
**Fourth, the runtime controls themselves have to be verifiable.** To cut
the cost of massive telemetry, Meta uses deduplication and sampling. That
suits macro-level analysis of operating patterns and anomaly hunting. But
for specific personal information processing that may need to be traced and
attributed, the system should also keep the necessary authorization source,
policy version, access target, data recipient, and final result in full.
Audit records can of course use identity references and asset identifiers.
There is no need to copy a full set of personal information into the logs
just to prove the protection works.
Figure 5 | How the rules stay in effect
Diagram from the original post, in Chinese. DCC's English reading follows.
*DCC's English reading (illustration of agent compliance design).* Four
supports: **substantive judgment of necessary scope**; **rule updates that
arrive promptly**; **locating and clearing memory and copies** when deletion
conditions are met; **necessary audit records that can be traced**. Together
they rest on one base: **every operation follows the rules currently in
force.**
In the end, these requirements have to be carried out by each organization
involved in the processing, according to its role. Who decides the purposes
and means of processing, who provides entrusted processing services, and who
actually controls the tools, the permissions, and the points where data
flows should all be clearly defined in system design and in contracts. Only
by turning the relevant compliance decisions into rules the system can
enforce, block on, and trace can each party's personal information
protection obligations actually be performed while agents run dynamically.
Back to the expense claim. The autonomy users really want from an agent is
for the system to choose steps and coordinate the task by itself, within
reasonable limits. For that autonomy to be compatible with personal
information protection, the boundaries of processing must stay tied to the
specific processing purpose, the minimum necessary scope of data, and clear
recipient conditions, and must carry through into data processing, memory
retention, and delegation between agents.
Meta's PrivacyLib pushes continuous runtime verification down into the
underlying data-access infrastructure. Extending rule checks along the same
lines to derived content, long-term memory, and chains of agent delegation
gives personal information protection in the age of agents an enforcement
path that runs through the whole task. **A task can unfold dynamically, but
processing authority must not expand by itself as data is read, generated,
saved, and handed on.** Only when every concrete operation is decided under
the rules in force at that moment, and every flow of information fully
carries the protective restrictions that apply to it, can the organizations
involved really meet their personal information protection obligations in
complex, shifting systems.
---
— *网安寻路人, 智能体处理个人信息的边界如何持续有效——从 Meta PrivacyLib
看个人信息保护的运行机制 (How Can the Boundaries of an AI Agent's Personal
Information Processing Stay Effective? Personal Information Protection at
Runtime, Seen Through Meta's PrivacyLib), October 28, 2026.
[Original (Chinese).](https://mp.weixin.qq.com/s/nN-CIEKLbSD_3zBigKPXpw)*
— Not legal advice.